I Marked Who Was Speaking by Ear, Then Graded the AI's Speaker Labels Against My Marks

A transcript without speaker names is hard to use. If an audio file has two people talking, I need to know which words came from which person. My pipeline can label speakers automatically. The question was whether I could trust the labels. I did not want to trust them just because the output looked clean. So I made an answer key by hand, and I let the computer grade itself against it. ...
October 22, 2026 · 6 min · VibePapa
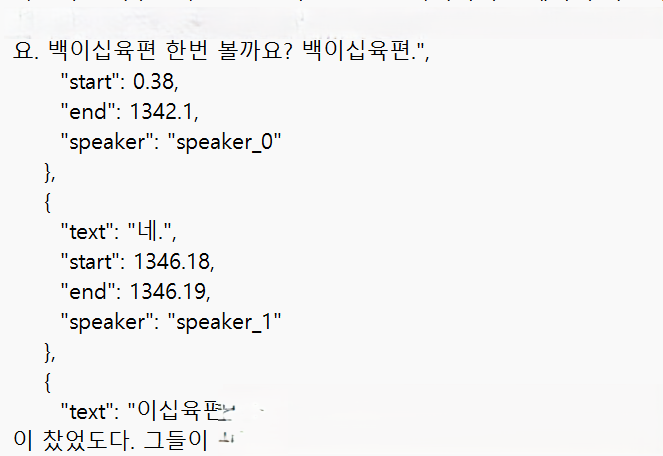
A transcript split into labeled speakers — speaker_0 and speaker_1 — with timestamps

Whisper vs ElevenLabs: When a Recording Has More Than One Voice

My wife listens to a Bible teacher every morning. After I built her an app to make that easier (the first post in this series), she asked for one more thing. It turned out to be the hardest part of the project. Could we also read his teachings, she said, not just hear them? Reading helps her study. She wanted the words on a screen. “Sure,” I thought. “I’ll just turn the audio into text.” How hard could it be? In 2026, turning speech into text is mostly a solved problem. ...

June 17, 2026 · 6 min · VibePapa