Keep What the Speaker Said: Checking a Sermon Transcript Against the Bible Without Letting the AI Rewrite It

A transcript is a record of what a person said. If an AI “fixes” it into what the person should have said, it is no longer a record. I learned this on my own archive of Korean sermon recordings. The Need: Fix the Mistakes, Keep the Speaker Speech-to-text gets Bible words wrong. It writes a hardship word for a different hardship word, a town name as nonsense, a book of the Bible as another book. For a searchable archive, that matters, because people search for those names. ...
October 22, 2026 · 7 min · VibePapa

Local Qwen vs Gemini for Fixing a Transcript: 50 Minutes Free vs 2.3 Minutes for 9 Cents

I like the idea of running my own AI. No bill, no data leaving my house. So when I needed to clean up a long transcript, I tried the local way first. The result changed my mind about when “free and local” is worth it. The Need: Speech-to-Text Gets Names Wrong Whisper turns a Korean sermon into text very well, but it makes a certain kind of mistake. It hears Bible words as ordinary words. A town name becomes a nonsense word. A book of the Bible becomes a different book. And one example I like: the Korean word for Psalms, sipyeon (시편), sounds almost like “ten pyeon” (10편). Whisper wrote “10” where the speaker said “Psalms”. ...

October 22, 2026 · 5 min · VibePapa

I Marked Who Was Speaking by Ear, Then Graded the AI's Speaker Labels Against My Marks

A transcript without speaker names is hard to use. If an audio file has two people talking, I need to know which words came from which person. My pipeline can label speakers automatically. The question was whether I could trust the labels. I did not want to trust them just because the output looked clean. So I made an answer key by hand, and I let the computer grade itself against it. ...

October 22, 2026 · 6 min · VibePapa

The Bug That Put Every Search Result 20 Minutes Off

In the post on search I gave you the clean version: type a word, get every place it was said, tap to jump to that moment. That’s true now. But I made it sound smooth, and for a while it wasn’t. The search had a bug that wore me down — and tracking it down taught me one of the more useful lessons in this series. The symptom was maddening. You’d search a word, see a result, tap “play from here” — and the audio would start playing twenty minutes before the word you searched for. The search found the right thing. It just sent you to the wrong place in the recording. Sometimes by seconds, sometimes by twenty whole minutes. ...

June 23, 2026 · 6 min · VibePapa
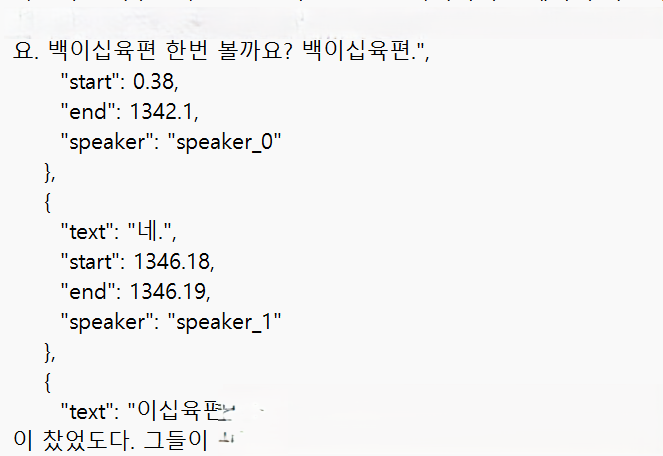
A transcript split into labeled speakers — speaker_0 and speaker_1 — with timestamps

Whisper vs ElevenLabs: When a Recording Has More Than One Voice

My wife listens to a Bible teacher every morning. After I built her an app to make that easier (the first post in this series), she asked for one more thing. It turned out to be the hardest part of the project. Could we also read his teachings, she said, not just hear them? Reading helps her study. She wanted the words on a screen. “Sure,” I thought. “I’ll just turn the audio into text.” How hard could it be? In 2026, turning speech into text is mostly a solved problem. ...

June 17, 2026 · 6 min · VibePapa